Migrating to Databricks is one of the most transformative moves a data-driven organization can make. The Databricks Lakehouse Platform promises unified analytics, faster time-to-insight, and dramatically simplified data infrastructure. But the road from legacy systems to a production-ready Databricks environment is rarely smooth.
Organizations that attempt migrations without the right strategy or without the right partner routinely encounter unexpected data quality issues, stalled timelines, cost overruns, and governance gaps that can set projects back by months. The good news? Every one of these challenges has a proven solution, and a skilled migration partner can make the difference between a transformation that delivers ROI and one that becomes a cautionary tale.
In this guide, we break down the most common Databricks migration challenges, the solutions that actually work, and the key criteria you should use when selecting a migration partner for your organization.
Why Databricks Migration Is More Complex Than It Looks
At first glance, a Databricks migration might seem like a lift-and-shift exercise: move your data pipelines, re-point your BI tools, and you’re done. In practice, the complexity compounds quickly. Most enterprise data environments have evolved organically over years, accumulating technical debt, undocumented dependencies, and a patchwork of tools that each require careful handling.
The Three Pillars of Migration Complexity
• Data Volume and Velocity – Petabyte-scale datasets require phased, orchestrated movement strategies that don’t disrupt live operations.
• Ecosystem Interdependencies – ETL pipelines, reporting layers, ML models, and operational applications often share data in ways that aren’t formally documented.
• Organizational Readiness – Teams must be upskilled on new tools, workflows, and governance models while continuing to deliver business value.
Top 5 Databricks Migration Challenges
Through our experience delivering Databricks migrations for organizations across industries, we have identified five challenges that consistently arise and that consistently catch teams off guard.
| ⚙️ Challenge 1: Legacy Data Pipeline ComplexityExisting Spark, Hadoop, or SQL-based pipelines often rely on platform-specific behaviors that do not translate directly to Databricks without re-engineering. | 🔍 Challenge 2: Schema Evolution & Data QualitySource systems with poorly enforced schemas produce inconsistent data that fails quality checks on a modern lakehouse, causing downstream failures. |
| 🔒 Challenge 3: Security & Access Control MigrationRe-creating fine-grained row- and column-level security policies, along with PII masking, in Databricks Unity Catalog requires careful planning. | 💰 Challenge 4: Cost Management & OptimizationWithout cluster policies, auto-termination rules, and job sizing best practices, Databricks costs can balloon significantly during and after migration. |
| 👥 Challenge 5: Skill Gaps & Change ManagementData engineers, analysts, and ML practitioners all need to ramp up on new tools, APIs, and workflows, a process that takes time and structured enablement. | 📐 Challenge 6: Workload PrioritizationDeciding which workloads to migrate first and in what order without disrupting business-critical reporting requires a rigorous assessment framework. |
Deep Dive: Legacy Pipeline Complexity
Legacy Hadoop MapReduce jobs and custom Spark applications built against older API versions frequently rely on deprecated functions, cluster-specific configurations, or undocumented side effects. When these pipelines are moved directly to Databricks without code review, they either fail outright or produce incorrect results silently, the worst possible outcome in a production environment.
The migration team must conduct a thorough pipeline inventory, classify jobs by complexity (low, medium, high-risk), and prioritize re-engineering for high-risk workloads before cutover.
Deep Dive: Security and Unity Catalog Migration
Databricks Unity Catalog is a powerful governance layer, but migrating from legacy Hive Metastore configurations, or from another cloud provider’s IAM model, requires mapping every permission including table-level, column-level, and row-filter policies to Unity Catalog’s three-level namespace (catalog.schema.table).
Organizations with PII data or industry compliance requirements (HIPAA, SOC 2, GDPR) need to validate that every policy is correctly replicated before the legacy system is decommissioned.
Deep Dive: Cost Management in Databricks
Databricks bills on DBUs (Databricks Units), and costs are highly sensitive to cluster type, cluster size, and job run duration. Teams migrating from on-premises Hadoop often underestimate cloud spend because they have no frame of reference for pay-per-use infrastructure.
Common cost leaks include all-purpose clusters left running between jobs, oversized worker fleets, and workloads that run on Premium-tier clusters when Standard-tier would suffice. A migration partner should build FinOps guardrails into the architecture from day one.
Proven Solutions for Each Migration Challenge
Solution 1: Phased Migration with a Workload Assessment
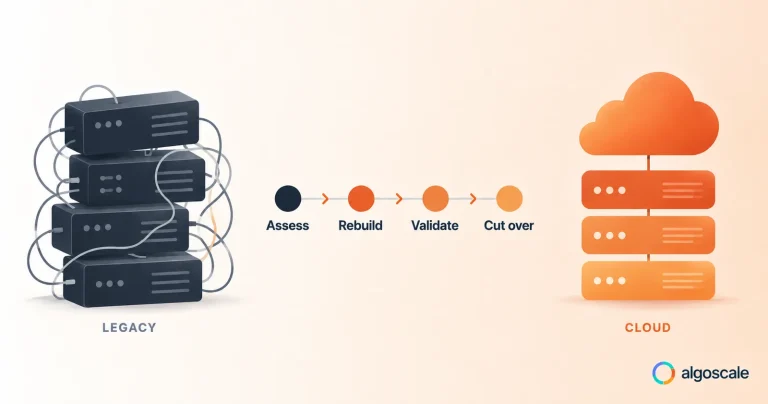
Rather than attempting a big-bang cutover, a phased migration strategy moves workloads in prioritized waves. The first step is a structured workload assessment that scores every pipeline on migration complexity, business criticality, and interdependency count. Low-complexity, high-value workloads migrate first to demonstrate early wins; high-complexity, high-risk workloads are re-engineered before migration with rigorous testing.
Solution 2: Schema Registry and Automated Data Validation
Implementing a schema registry (such as Confluent Schema Registry or Delta Lake schema enforcement) ensures that data quality issues are caught at the point of ingestion rather than discovered downstream. Automated validation pipelines should run after each migration wave to compare row counts, null rates, and statistical distributions between the source and target environments.
Delta Lake’s ACID transaction support provides an additional safety net: if a migration step fails, the table state automatically rolls back to its last consistent version.
Solution 3: Unity Catalog Governance Blueprint
A Unity Catalog governance blueprint should be designed before a single table is migrated. This blueprint defines the catalog and schema hierarchy, maps legacy permissions to Unity Catalog privileges, and establishes data classification tags for PII, sensitive, and public data. Column-level masking policies and row-level security filters should be tested in a staging environment before being applied to production.
Solution 4: FinOps Architecture for Databricks
Cost management on Databricks is an architectural discipline, not an afterthought. Best practices include using job clusters instead of all-purpose clusters for scheduled workloads, enabling cluster auto-termination, right-sizing worker pools based on profiling data, and using Spot/Preemptible instances for fault-tolerant batch jobs. Budget alerts and cost attribution tags enable teams to track spend by project, team, and workload from day one.
• Use job clusters for scheduled workloads (never all-purpose clusters)
• Enable auto-termination: 30-minute idle timeout as a baseline
• Use Spot instances for batch jobs with retry logic
• Implement cluster policies to enforce cost guardrails organization-wide
• Set up budget alerts at 75% and 90% of monthly thresholds
Solution 5: Structured Enablement and Change Management
A migration is only successful if the teams using the new platform are confident and productive. A structured enablement plan should begin 4-6 weeks before the first workload migration and include role-specific training tracks for data engineers (PySpark, Delta Lake, MLflow), analysts (SQL Warehouse, Databricks SQL, notebooks), and ML practitioners (AutoML, Feature Store, Model Serving).
Change management is equally important: clear communication about timelines, early involvement of power users as internal champions, and a feedback loop for reporting issues accelerate adoption dramatically.
What to Look for in a Databricks Migration Partner

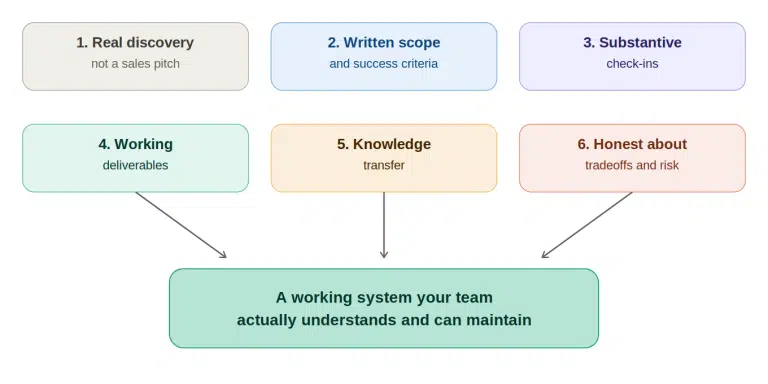
Not all Databricks migration partners are created equal. The partner you choose will have an outsized impact on migration speed, final architecture quality, post-migration costs, and the long-term health of your data platform. Here is the framework we recommend for evaluating potential partners.
1. Technical Certifications and Hands-On Expertise
A credible Databricks migration partner should hold current Databricks certifications including Databricks Certified Associate and Professional Developer, Databricks Certified Data Engineer, and Databricks Certified ML Professional with certifications held by the engineers who will actually work on your project, not just pre-sales staff.
Beyond certifications, look for demonstrated hands-on experience with the specific workload types relevant to your migration: streaming, batch, ML, or SQL analytics.
2. Proven Migration Methodology
A strong partner should be able to articulate a clear, repeatable migration methodology, not a vague promise to figure it out as they go. Ask for a sample workload assessment template, a migration wave planning document, and a post-migration validation checklist. Partners who have delivered multiple migrations will have refined tooling and documentation for each of these steps.
3. Industry-Specific Experience
Databricks migrations for healthcare organizations involve different compliance requirements than those for financial services firms or e-commerce companies. A partner with industry-specific experience will already understand the relevant regulatory landscape (HIPAA, SOC 2, PCI DSS), the common data models in your industry, and the performance patterns of your workload types.
4. Cloud Platform Depth
Databricks runs on AWS, Azure, and GCP, and the optimal architecture differs by cloud. A partner deeply experienced in your cloud platform will ensure that the surrounding infrastructure storage, networking, IAM, CI/CD pipelines is built correctly from the start. Misaligned cloud architecture is a leading cause of post-migration performance issues and unexpected costs.
5. Post-Migration Support Model
Migration is the beginning, not the end. Your partner should offer a structured post-migration support model that includes performance optimization, cost tuning, governance reviews, and platform updates as Databricks releases new features. Avoid partners who treat migration as a one-time project with no ongoing relationship.
Partner Evaluation Scorecard
Use this criteria framework when comparing Databricks migration partners:
| Criteria | What Good Looks Like | Red Flags |
| Databricks Certifications | Team-level certifications across DE, ML, and SQL tracks; verified on partner locator | Only pre-sales staff are certified; certifications are outdated |
| Migration Methodology | Documented phased approach with workload assessment templates and validation checklists | Vague project plan; no prior migration documentation available |
| Industry Experience | Case studies in your vertical with measurable outcomes (cost reduction, time-to-insight) | Generic references with no industry-specific detail |
| Cloud Platform Depth | Advanced Partner status on your cloud (AWS/Azure/GCP) with architecture blueprints | Limited cloud architecture experience; relies solely on Databricks defaults |
| FinOps Capability | Dedicated cost modeling, cluster policy design, and ongoing spend optimization | No cost management framework; cost optimization treated as an afterthought |
| Post-Migration Support | Defined SLAs, dedicated support team, quarterly platform reviews included | Support is ad hoc; no SLA commitments; handoff is immediate after go-live |
Why AlgoScale Is Your Ideal Databricks Migration Partner
At AlgoScale, we have built our practice around one core belief: great data engineering is the foundation of every high-performing, data-driven organization. Our Databricks migration services are designed to minimize risk, accelerate time-to-value, and leave your team with a platform they understand and can evolve independently.
Our Migration Framework
AlgoScale’s four-phase migration framework has been refined across engagements spanning financial services, logistics, healthcare, and SaaS:
• Phase 1 – Discovery and Assessment: Full workload inventory, dependency mapping, and business priority scoring (2-3 weeks)
• Phase 2 – Architecture and Governance Design: Unity Catalog blueprint, FinOps architecture, CI/CD pipeline design, and cluster policy framework (2-4 weeks)
• Phase 3 – Phased Workload Migration: Wave-by-wave migration with automated validation, stakeholder demos, and rollback readiness at every stage (6-16 weeks depending on scope)
• Phase 4 – Optimization and Enablement: Performance tuning, cost optimization, team training, and knowledge transfer (4-6 weeks)
Our Technical Differentiators
Post-Migration Support
Every AlgoScale migration engagement includes a 90-day post-go-live support period with dedicated engineering resources, monthly performance and cost reviews, and proactive monitoring of your Databricks environment. After the initial support period, clients can transition to our managed services model for ongoing optimization and platform governance.
Conclusion – give a proper headline here
Databricks is a genuinely powerful platform and a migration to Databricks, done right, can unlock capabilities that transform the way your organization works with data. But ‘done right’ requires a realistic understanding of the challenges involved, a structured approach to each one, and a partner with the expertise, methodology, and commitment to see the project through to success.
When evaluating migration partners, look beyond promises and evaluate the specifics: certifications, documented methodology, industry experience, cloud platform depth, FinOps capability, and post-migration support. The partner who scores well across all six criteria is the partner who will deliver a Databricks environment your team can be proud of.