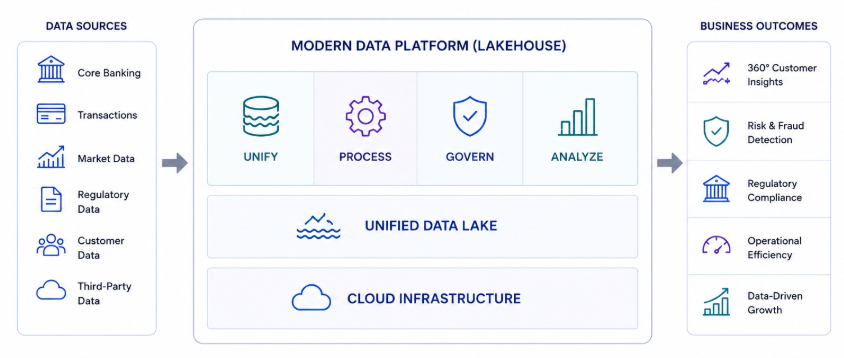

Something fundamental has shifted in the way enterprise data teams are thinking about their infrastructure. After more than a decade of living with the uncomfortable tradeoff between the analytical power of data warehouses and the storage flexibility of data lakes, a growing number of the world’s largest organizations have found a third path: the data lakehouse.
In 2026, the enterprise data lakehouse is no longer an architectural experiment. It is the production platform of choice for organizations as diverse as global banks, healthcare systems, manufacturing conglomerates, retail giants, and SaaS scale-ups. The reasons are consistent: lower total cost of ownership, better support for AI and machine learning workloads, unified data governance, and the elimination of the data silos that have plagued enterprise analytics for years.
This guide explains the full case for enterprise data lakehouse adoption, the problems it solves, the platforms that deliver it, the use cases it unlocks, and what best-in-class lakehouse migration services and implementation look like in practice.
The Breaking Point: What’s Wrong with the Traditional Data Stack
The modern enterprise data stack was built in layers. A data warehouse for structured analytics, a data lake for raw storage, a separate ML platform for data science, an operational database for transactional workloads. Each layer was purpose-built, and each layer was best-in-class at the time it was deployed. Together, they created one of the most expensive, fragile, and frustrating architectures in enterprise technology.
The Data Warehouse Problem
Cloud data warehouses Snowflake, Google BigQuery, Amazon Redshift deliver exceptional SQL query performance on structured data. But they were not designed for the workloads that now define competitive advantage: machine learning model training, streaming analytics, unstructured data processing, and the massive data volumes that modern businesses generate. Storing petabytes of raw event data in a proprietary cloud data warehouse is prohibitively expensive. Running ML training jobs on warehouse computers is technically possible but economically irrational.
The deeper problem is vendor lock-in. Data stored in proprietary warehouse formats cannot be read by external tools without export and export at petabyte scale is neither fast nor cheap. Enterprises that have scaled into a cloud data warehouse find themselves negotiating renewal contracts from a position of structural dependency.
The Data Lake Problem
The response to data warehouse costs and limitations was the data lake: store everything cheaply in object storage (Amazon S3, Azure Data Lake Storage, Google Cloud Storage) in open formats, and query it with Spark, Presto, or Hive. The concept was sound. The execution was consistently painful. Data lakes without disciplined management become data swamps: inconsistent schemas, duplicate records, no transactional guarantees, failed jobs that leave partial data in an unknown state, and no lineage to explain where any particular number came from.
ACID transactions guarantee that writes are atomic, consistent, isolated, and durable and do not exist on a raw data lake. A Spark job that fails mid-write leaves the table in a corrupted state. Concurrent readers may see inconsistent data. These are not theoretical concerns: they are operational realities that enterprise data engineering teams deal with daily on unmanaged data lakes.
What Is an Enterprise Data Lakehouse and Why It Resolves the Tradeoff

A data lakehouse is a data architecture that provides ACID transaction guarantees, schema enforcement, and query performance comparable to a data warehouse on top of low-cost open-format storage in a cloud object store. The term was coined by Databricks researchers and formalized in a 2021 CIDR paper that has since become one of the most cited documents in enterprise data architecture.
The architectural breakthrough is the open table format: a metadata and transaction log layer that sits on top of standard Parquet files in object storage, adding the transactional guarantees and query optimization features that make warehouse-grade analytics possible at data-lake-grade costs.
Data Warehouse vs. Data Lake vs. Lakehouse: The Definitive Comparison
The comparison below covers the dimensions that matter for enterprise architecture decisions:
| Capability | Data Warehouse | Data Lake | Data Lakehouse |
| Storage Cost at Scale | ❌ Expensive (compute-storage coupling) | ✅ Low (object storage) | ✅ Low (open format on object storage) |
| ACID Transactions | ✅ Full ACID | ❌ None | ✅ Full ACID (via Delta Lake / Iceberg) |
| Schema Enforcement | ✅ Strict | ❌ Schema-on-read only | ✅ Flexible + enforced |
| SQL Analytics Performance | ✅ Excellent | ⚠️ Possible but complex | ✅ Excellent (Photon / vectorised engines) |
| ML / AI Workloads | ⚠️ Limited | ✅ Good | ✅ Native (MLflow, Feature Store) |
| Streaming Support | ⚠️ Batch-oriented | ⚠️ Complex setup | ✅ Unified batch + streaming |
| Unstructured Data | ❌ Not supported | ✅ Yes | ✅ Yes |
| Data Governance | ✅ Strong | ❌ Weak | ✅ Unity Catalog / Purview / Polaris |
| Open Standards | ❌ Proprietary format | ✅ Open files | ✅ Open table format + open files |
| Vendor Lock-in | ❌ High | ✅ Low | ✅ Low |
| Data Lineage | ⚠️ Partial | ❌ Manual | ✅ Automated column-level lineage |
| Time Travel / Versioning | ❌ Not supported | ❌ Not supported | ✅ Built-in (Delta / Iceberg) |
The Business Case: Why Modern Enterprises Are Making the Move
The decision to migrate to a lakehouse architecture is not primarily a technology decision, it is a business decision driven by cost, competitive pressure, and the strategic imperative to become an AI-enabled organization. The following drivers consistently appear across enterprise evaluations.
| 💰 Eliminate the Data Warehouse Cost CurveCloud data warehouses scale costs with data volume in ways that compound over time. A lakehouse decouples storage (cheap object storage) from compute (elastic and shutdownable), delivering 30–60% infrastructure cost reductions at petabyte scale without sacrificing query performance. | 🏗️ Eliminate Data Silos Across the EnterpriseA unified enterprise data lakehouse becomes the single authoritative source for every data domain transactional, analytical, ML feature, and streaming eliminating the reconciliation overhead of multi-platform architectures. |
| ⚡ Real-Time Analytics Enterprise-WideStreaming analytics at enterprise scale customer behaviour signals, IoT telemetry, financial transactions, logistics events become first-class citizens on a lakehouse, not a separate system bolted onto the batch analytics stack. | 🤖 Enterprise AI and ML ReadinessLakehouse architectures natively support the full ML lifecycle: governed training data, experiment tracking, model registry, and production serving all on the same platform as the business’s analytical workloads. |
| 🛡️ Unified Data Governance at ScaleOne governance model across all data types structured, semi-structured, unstructured with automated lineage, column-level masking, and audit trails. Governance retrofitted across seven systems is governance that consistently has gaps. | 🌍 Open Standards Eliminate Vendor Lock-inData stored in Delta Lake or Apache Iceberg format is readable by any compatible tool. Enterprises retain data portability and the right to switch platforms without a petabyte-scale migration project. |
| 📊 Self-Service Analytics for Every TeamSQL-native interfaces (Databricks SQL, Microsoft Fabric SQL analytics endpoint) enable business analysts to query lakehouse data directly without engineering involvement, accelerating the time from question to insight. | 🔄 Simplified Data Engineering OperationsOne platform to operate, monitor, and maintain instead of seven. Data engineering teams report 40–60% reductions in pipeline maintenance overhead after consolidating on a unified lakehouse architecture. |
Leading Lakehouse Platforms: Databricks, Microsoft Fabric, Iceberg, and Snowflake
The enterprise data lakehouse market has matured rapidly. Multiple credible platforms now deliver production-grade lakehouse capabilities, each with distinct strengths, open table format preferences, and cloud ecosystem alignments. The platform decision is one of the most consequential choices in an enterprise data platform modernization services engagement.
| Databricks (Delta Lake) | Microsoft Fabric (OneLake) | Apache Iceberg (AWS / BigLake) | Snowflake (Iceberg Tables) |
| Format: Delta LakeCloud: AWS · Azure · GCPStrength: Best-in-class ML/AI + Photon SQLBest for: AI-first & multi-cloud | Format: Delta ParquetCloud: Azure-nativeStrength: Deep M365 + Power BI integrationBest for: Azure-invested enterprises | Format: Apache IcebergCloud: AWS · GCPStrength: Maximum interoperabilityBest for: Multi-engine open architectures | Format: Apache IcebergCloud: AWS · Azure · GCPStrength: SQL ease + managed operationsBest for: SQL-centric analytics teams |
Databricks Lakehouse: Delta Lake Architecture
Databricks invented the lakehouse concept and remains the most complete implementation of it. The Databricks lakehouse is built on Delta Lake an open-source ACID transaction layer on Parquet with Photon (a vectorised C++ query engine), Unity Catalog (unified governance), MLflow (ML lifecycle), Delta Live Tables (declarative pipelines), and Databricks SQL (serverless analytics) forming an integrated stack. Databricks consistently tops performance benchmarks for both data transformation and SQL analytics workloads, and its AI and ML capabilities are the most mature in the market.
• Open source Delta Lake: readable by Spark, Flink, Presto, Trino, and any Parquet-compatible engine
• Photon vectorised engine: 2–12x query acceleration over standard Spark on analytical workloads
• Unity Catalog: column-level lineage, PII masking, row-level security, and Delta Sharing for cross-platform data access
• Best suited for: AI-intensive workloads, multi-cloud deployments, financial services, healthcare, and capital markets
Microsoft Fabric Lakehouse: OneLake Architecture
Microsoft Fabric is Microsoft’s unified analytics platform, released in 2023 and now the default recommendation for Azure-invested enterprises. Fabric’s OneLake is a single logical data lake for the entire organization; every workload in Fabric (data engineering, data science, real-time analytics, Power BI) reads and writes to OneLake in Delta Parquet format. The integration with Microsoft 365, Azure Active Directory, Microsoft Purview (governance), and Power BI is unmatched in depth.
• OneLake Shortcuts: virtual links to data in ADLS, AWS S3, or GCS without data movement
• Microsoft Purview integration: unified governance across Fabric, Azure Data Factory, and Azure Synapse
• Direct Lake mode: Power BI reads directly from OneLake Delta files without import or DirectQuery limitations
• Best suited for: Azure-native enterprises with significant Power BI and M365 investment
Apache Iceberg Lakehouse: AWS Glue, Google BigLake, and Polaris
Apache Iceberg is an open table format governed by the Apache Software Foundation, with no single vendor owner. AWS Glue Data Catalog, Amazon Athena, Amazon Redshift Spectrum, Google BigLake, and Apache Spark all support Iceberg natively. The Apache Polaris project (Snowflake-donated, now Apache incubating) provides an open Iceberg catalog server for multi-engine architectures. Iceberg’s spec supports hidden partitioning, partition evolution, snapshot isolation, and row-level deletes comparable to Delta Lake in functional terms.
• AWS Glue lakehouse: managed Iceberg tables with Athena, EMR, and Redshift Spectrum querying the same data
• Google BigLake: unified storage management for BigQuery and Spark on Google Cloud Storage Iceberg tables
• Maximum interoperability: any engine supporting Iceberg can read and write the same tables
• Best suited for: multi-cloud strategies, avoidance of Databricks/Snowflake dependency, AWS-native architectures
Snowflake Lakehouse: Iceberg Tables and Hybrid Architecture
Snowflake’s lakehouse strategy is built on Iceberg Tables customer-managed storage in Iceberg format that Snowflake queries via its engine. This hybrid approach gives Snowflake customers the cost economics of object storage for cold and large datasets while retaining Snowflake’s SQL ease and managed operations model. Snowflake also offers Polaris catalog integration for cross-engine data access.
• External Iceberg tables: data lives in customer-controlled S3/ADLS; Snowflake engine queries without proprietary format
• Iceberg + Snowpark: ML and data engineering in Python/Java/Scala on Iceberg data within Snowflake compute
• Best suited for: Snowflake-invested enterprises expanding beyond SQL analytics into ML and streaming use cases
Lakehouse Architecture for Enterprise Use Cases
Enterprise BI and Self-Service Analytics
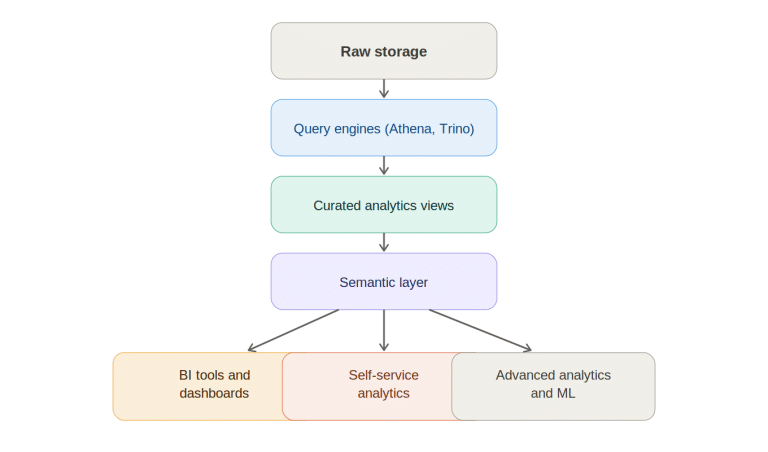
The lakehouse’s Gold layer is purpose-built for BI consumption. Curated, business-ready aggregates revenue by product and region, customer cohort retention, operational KPIs are served via Databricks SQL, Microsoft Fabric SQL analytics endpoint, or Google BigLake to any compatible BI tool (Power BI, Tableau, Looker, ThoughtSpot) with sub-second query latency on properly optimised Delta or Iceberg tables. Business analysts query these tables directly, without engineering involvement, using the SQL skills they already have.
Delta Lake’s time-travel capability enables point-in-time reporting; a single query can compare today’s metrics against any historical snapshot without maintaining separate historical snapshots or slowly changing dimension tables.
Real-Time Streaming Analytics at Enterprise Scale
Streaming analytics enterprise workloads IoT sensor streams, clickstream data, financial transactions, logistics events are first-class citizens on a lakehouse. Spark Structured Streaming ingests events into Bronze Delta or Iceberg tables with sub-second latency. The same table that receives streaming writes serves concurrent batch readers and SQL queries with no separate streaming storage layer, no data duplication, no reconciliation between real-time and historical views.
Apache Flink and Amazon Kinesis Data Analytics (for Iceberg architectures) extend streaming support to high-throughput, low-latency use cases where Spark’s micro-batch model is not sufficient.
Enterprise AI and Machine Learning on the Lakehouse
The enterprise AI data platform is the most compelling driver of lakehouse adoption in 2025–2026. Organisations that have operationalised AI on a lakehouse report dramatically faster model development cycles because data scientists work directly on governed, quality-controlled lakehouse data rather than on bespoke data extracts that go stale between refresh cycles. MLflow (Databricks), Microsoft Fabric’s AI and ML workloads, and the broader open-source ML ecosystem all integrate natively with Delta Lake and Iceberg table formats.
• Feature Store: pre-computed ML features stored as Delta tables, shared across models and teams
• Training data versioning: time-travel enables reproducible model training on historical data snapshots
• Model governance: MLflow Model Registry tracks every model version, its training data, and its performance metrics
• Agentic AI: Databricks Agent Bricks enables enterprise AI agents to access low-latency feature pipelines alongside historical data
Data Mesh with a Lakehouse Foundation
Data mesh is an organizational architecture pattern that distributes data ownership to domain teams each domain owns, manages, and publishes its own data products. A lakehouse architecture is the natural technical substrate for a data mesh implementation: Unity Catalog or Apache Polaris provides the federated governance layer, Delta Sharing enables cross-domain data product publishing without data movement, and the shared object storage layer eliminates the infrastructure complexity of truly distributed data ownership.
Data mesh and data lakehouse are not competing architectures, they are complementary. The lakehouse is the how; the data mesh is the who and what.
Open Table Formats: The Engine of Lakehouse Portability
Open table formats are the technical foundation that makes the lakehouse possible. They are metadata and transaction log layers that add database-grade capabilities ACID transactions, schema enforcement, time travel, and partition management to standard Parquet files in object storage. The three major open table formats are Delta Lake, Apache Iceberg, and Apache Hudi.
| Feature | Delta Lake | Apache Iceberg | Apache Hudi |
| Primary Backer | Linux Foundation / Databricks | Apache Software Foundation | Apache Software Foundation / Onehouse |
| ACID Transactions | ✅ Full | ✅ Full | ✅ Full |
| Time Travel | ✅ VERSION / TIMESTAMP AS OF | ✅ Snapshot queries | ✅ Incremental queries |
| Schema Evolution | ✅ Add, rename, drop columns | ✅ Full schema evolution | ✅ Schema on write |
| Partition Evolution | ⚠️ Requires table replacement | ✅ Hidden partitioning + evolution | ✅ Supported |
| Row-Level Updates/Deletes | ✅ MERGE, UPDATE, DELETE | ✅ Full row-level ops | ✅ Optimised for upserts |
| Multi-Engine Support | ✅ Spark, Flink, Presto, Trino, DuckDB | ✅ Widest engine support | ✅ Spark, Flink, Hive |
| Catalog Requirement | Unity Catalog / HMS / Glue | Polaris / Glue / Nessie / REST | HMS / Glue |
| Best For | Databricks-centric, ML-heavy workloads | Maximum portability, AWS/GCP native | High-frequency upsert workloads (CDC) |
Data Governance in the Enterprise Lakehouse
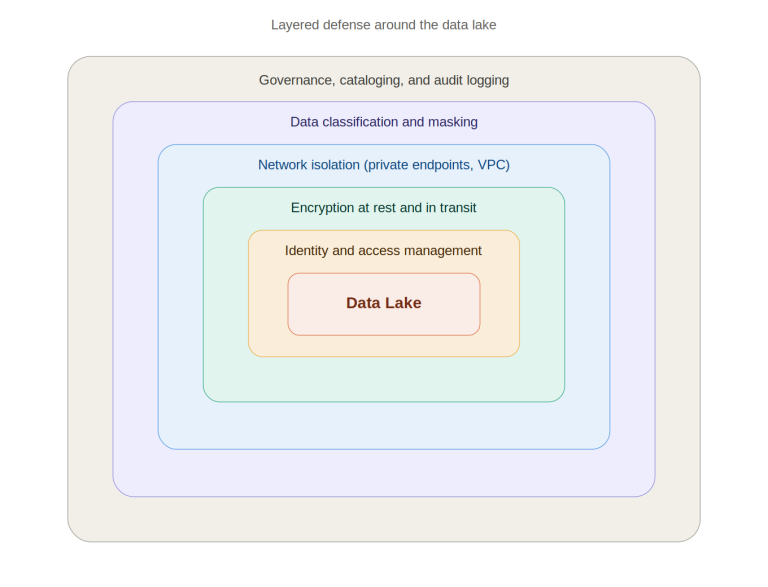
Data governance is not a feature that can be bolted onto a lakehouse after deployment it must be designed into the architecture from the start. Enterprise data governance requirements include automated data lineage, fine-grained access control, data quality monitoring, data cataloguing, and compliance with regulations ranging from GDPR and CCPA to BCBS 239 and HIPAA. Each of the major lakehouse platforms addresses this differently.
| Governance Capability | Databricks Unity Catalog | Microsoft Purview + Fabric | Apache Polaris / Gravitino |
| Automated Column Lineage | ✅ End-to-end, queryable | ✅ Within Fabric workloads | ⚠️ Developing |
| Dynamic Data Masking | ✅ Column-level, role-based | ✅ Via Purview sensitivity labels | ⚠️ Via engine implementation |
| Row-Level Security | ✅ Row filters in Unity Catalog | ✅ Via Power BI RLS + warehouse | ⚠️ Engine-specific |
| Audit Logging | ✅ System tables, fully queryable | ✅ Microsoft Purview audit logs | ✅ Iceberg REST catalog audit |
| Cross-Platform Data Sharing | ✅ Delta Sharing (open protocol) | ✅ OneLake Shortcuts | ✅ Iceberg REST cross-catalog |
| AI / ML Governance | ✅ MLflow Model Registry integration | ✅ Fabric AI workload governance | ⚠️ Framework-specific |
| Multi-Cloud Governance | ✅ Federated workspace model | ⚠️ Azure-primary | ✅ Open catalog federation |
The ROI of Moving to a Lakehouse: Cost, Performance, and Agility
Quantifying the return on investment from a data lakehouse migration requires looking across three dimensions: infrastructure cost reduction, performance improvement, and organisational agility gains. The benchmarks below represent reported outcomes from enterprises that have completed lakehouse migrations drawn from Databricks customer case studies, Microsoft Fabric reference architectures, and AlgoScale engagement experience.
| Metric | Legacy Stack Baseline | Lakehouse Outcome |
| Storage cost at petabyte scale | $230–$480/TB/month (warehouse) | $20–$40/TB/month (object storage + table format) |
| Risk data aggregation time (BCBS 239) | 48–72 hours | 2–4 hours on Databricks lakehouse |
| ML model training cycle | 2–4 weeks (data extraction + prep) | 2–5 days (governed lakehouse training data) |
| Pipeline maintenance overhead | 60–70% of data engineering capacity | 25–35% after lakehouse consolidation |
| Self-service query latency | Hours (warehouse queue backlog) | Seconds (Databricks SQL serverless) |
| Time-to-market for new data products | 4–8 weeks | 1–2 weeks (Unity Catalog + DLT pipelines) |
| Compliance reporting preparation | Manual, 3–5 days per cycle | Automated pipelines, same-day delivery |
| Duplicate data platform contracts | 3–7 separate vendor contracts | 1–2 platform contracts (40–60% savings) |
Lakehouse Migration Services: What the Journey Looks Like

A data platform modernization services engagement for enterprise lakehouse migration is not a lift-and-shift operation. It requires careful assessment of the current state, deliberate architecture design, phased execution to minimise operational disruption, and a post-migration optimisation programme to realise the full ROI of the new platform. The following phase model reflects best practice for enterprise lakehouse migration services engagements.
| Phase | Duration | Deliverables | Services Included |
| 01 | Weeks 1–3 | Workload inventory, source system map, data quality baseline, platform selection recommendation, business case and ROI model | Data Lakehouse Consulting • Platform Assessment |
| 02 | Weeks 3–6 | Target architecture blueprint, governance design (Unity Catalog / Purview / Polaris), medallion layer design, FinOps model, CI/CD pipeline design | Lakehouse Architecture Consulting • Governance Design |
| 03 | Weeks 5–12 | Cloud infrastructure provisioning, catalog deployment, Auto Loader ingestion, Bronze and Silver layers for priority domains, data quality expectations | Lakehouse Implementation Services • Data Engineering Services |
| 04 | Weeks 10–20 | Gold-layer aggregations, BI tool connectivity, SQL dashboard deployment, self-service analytics enablement, streaming pipeline build | Data Platform Modernization Services • BI Migration |
| 05 | Weeks 16–24 | ML infrastructure (MLflow / Feature Store), model migration, serving endpoint deployment, model governance documentation | Enterprise AI Data Platform • MLOps Services |
| 06 | Weeks 22–26 | Performance optimisation, FinOps review, team training (all roles), documentation, decommission of legacy platforms | Cloud Data Migration Services • Enablement |
| 07 | Ongoing | Platform operations, cost monitoring, governance reviews, platform upgrades, new use case development | Data Lakehouse Managed Services • Support |
What to Look for in Lakehouse Migration Services and Consulting
Not all data lakehouse consulting providers have the depth to deliver enterprise-scale migrations safely. When evaluating providers, the criteria below should be non-negotiable:
• Platform certifications: Databricks-certified engineers (Data Engineering, ML, SQL tracks); Microsoft Fabric expertise for Azure environments
• Documented migration methodology: a proven, repeatable phase model with deliverable templates and risk mitigation playbooks for each wave
• FinOps capability: cost modelling before migration, cluster policy design during build, and ongoing spend optimisation as a managed service
• Governance-first approach: Unity Catalog or Purview design completed before the first table is created not retrofitted after go-live
• Reference clients: referenceable case studies from enterprises in your industry vertical with comparable data volumes and complexity
• Post-migration support: defined SLA, dedicated engineering resources, and a managed services model for ongoing platform operations
AlgoScale: Enterprise Lakehouse Implementation and Data Engineering Services
AlgoScale is a data engineering and analytics consulting firm specialising in enterprise lakehouse implementation services across Databricks, Microsoft Fabric, and Apache Iceberg architectures. Our practice is built around a single conviction: the quality of your data platform determines the quality of every business decision made from it. We build lakehouses that are fast, governed, cost-optimised, and designed to evolve as your business grows.
Our Technology Partnerships and Expertise
| 🔷 Databricks Lakehouse (Delta Lake)Full-stack Databricks delivery: Unity Catalog, Delta Live Tables, Databricks SQL, MLflow, Model Serving, Workflows. Certified across Data Engineering, ML, and SQL Analytics tracks. | 🟦 Microsoft Fabric (OneLake / Delta)End-to-end Fabric implementations: Data Engineering, Data Science, Real-Time Analytics, Power BI Direct Lake. Deep integration with Azure Data Lake, Purview, and M365. |
| 🌐 Apache Iceberg (AWS / GCP / Multi-Cloud)Open architecture Iceberg deployments on AWS Glue, Amazon Athena, EMR, Google BigLake, and Apache Polaris. Maximum portability for multi-cloud enterprise strategies. | 🔁 Hybrid Databricks + Microsoft FabricDual-platform architectures that leverage Databricks for ML and streaming workloads and Microsoft Fabric for Power BI-centric BI unified under a single governance and data-sharing layer. |
| 🛡️ Lakehouse Governance and ComplianceUnity Catalog blueprints, data classification frameworks, PII masking policies, BCBS 239 lineage compliance, GDPR right-to-erasure architecture, and model risk management documentation. | 💰 FinOps and Cost OptimisationCluster policy design, compute right-sizing, storage lifecycle management, and monthly spend reviews. Clients consistently achieve 30–50% infrastructure cost reductions within 12 months of go-live. |
Our Delivered Lakehouse Outcomes
• Capital markets firm: VaR calculation time from 6 hours to 18 minutes; full Delta Lake architecture with Unity Catalog governance
• Healthcare system: HIPAA-compliant patient data lakehouse; PHI exposure eliminated through column masking; clinical analytics cycle from 3 weeks to 4 hours
• Manufacturing enterprise: 50,000+ IoT sensor streams unified on Databricks lakehouse; predictive maintenance model reduces downtime by 41%
• Retail & e-commerce: Customer 360 lakehouse; recommendation model accuracy improved 28%; marketing attribution from 2 days to 30 minutes
• Financial services (banking): BCBS 239-compliant risk data aggregation platform; reporting cycle from 48 hours to 3 hours
• SaaS company: product analytics lakehouse on Microsoft Fabric; data engineering headcount frozen despite 5x data volume growth
Conclusion: The Lakehouse Is Not a Trend It Is the Destination
The movement of modern enterprises to lakehouse architecture reflects something deeper than a technology preference cycle. It reflects a fundamental reckoning with the structural costs financial, operational, and competitive of running fragmented data infrastructure at scale.
The enterprise data lakehouse resolves the core tradeoff that has defined data architecture for a decade: storage economics vs. analytical capability. With open table formats (Delta Lake, Apache Iceberg, Apache Hudi) providing ACID guarantees on object storage, governance platforms (Unity Catalog, Microsoft Purview, Apache Polaris) providing enterprise-grade data management, and unified compute platforms (Databricks, Microsoft Fabric, AWS Glue) delivering performance benchmarks that match or exceed purpose-built warehouses, the case for the lakehouse is now unanswerable.
The question for enterprise data leaders in 2026 is not whether to move to a lakehouse architecture. It is which platform to move to, in what sequence, and with which implementation partner. Get those decisions right, and the lakehouse becomes the platform that powers your organisation’s analytics, AI, and competitive capabilities for the next decade.
| ◆ | Start Your Enterprise Lakehouse Journey with AlgoScaleAlgoScale offers a complimentary Enterprise Lakehouse Readiness Assessment a 3-hour structured workshop where our architects evaluate your current data stack, identify your highest-value migration opportunities, recommend the right platform mix (Databricks, Microsoft Fabric, or Iceberg), and design your initial migration roadmap.We also offer a Data Platform Modernization Cost Modelling session, a quantified analysis of your current infrastructure spend versus projected lakehouse costs, built on your actual data volumes and workload profiles.Contact us: hello@algoscale.com | algoscale.com/enterprise-lakehouse |
© 2026 AlgoScale. All rights reserved. AlgoScale is a data engineering and analytics consulting firm specialising in Databricks, Microsoft Fabric, Apache Iceberg, and open lakehouse architectures for modern enterprises.