All services
All industries

Data Lake Consulting Services

Data lake consulting helps you design, build, migrate and govern one central store for all your structured, semi-structured and unstructured data, on AWS, Azure, Databricks or Microsoft Fabric.

Our Partners

Enterprises that trust Algoscale for data lake consulting services

What is a data lake?

A data lake is one central store that keeps all your data (tables, logs, files, images and events) in its original format at low cost. Teams can clean it, query it and feed it to dashboards and AI models without first copying it into separate systems. It isn’t an ETL tool: pipelines load data into the lake, and the lake holds it.

Why Are Data Lake Consulting Services Required?

Most companies end up with a lake, a warehouse and a pile of spreadsheets that each show a different number. Data with no owner turns the lake into a swamp, analysts spend their week hunting for the right file, and AI projects stall on data nobody trusts. A consultant fixes the foundation first: one governed platform, clear data ownership, and pipelines that keep data clean as volumes grow.

Therefore, it is really important that you take actions to prevent your business from moving forward. Waiting for the next crisis to sort your data out is how a small problem turns into an expensive one. The work costs less before you need the answer than after.

You need a data lake when your team puts in efforts to hunt down data from isolated silos rather than analysing it. Every hour spent chasing a file across systems is an hour nobody spends asking why the numbers moved. One landing place ends the hunt.

You have to keep systems ready so that you can outrun your slow reporting systems and feed raw information into modern AI tech. Older stacks were built for monthly cycles, not for a question asked on a Tuesday afternoon. Your models need the raw data too, in a form they can actually read.

If you cannot access your data insights, ultimately your business growth will suffer. You have already paid to collect and store all of it. An insight you cannot reach in time counts the same as one you never had.

Our data lake and lakehouse consulting services.

Our track record involves providing data lake consulting services across countries like US, UK, Australia. We offer services across a full lifecycle; starting from strategy, architecture, implementation, migration, and long-term managed operations. It is important for us to know your intent regarding the pool of data you have. This will assist us to make you reach your goal easily.

Data Lake Strategy Consultation

We start our process by understanding your current system, compliance obligations, and the end goal for your data. We compare Apache Iceberg, Delta Lake, and Apache Hudi against your existing data ingestion patterns. Finally, we create a strategy personalised for your business, that helps you track and manage data with safety and ease.
Data Lake Implementation Services

We design and build secure data lakes that can easily grow alongside your business. Whether you prefer to work on AWS, Microsoft Azure, or Google Cloud, we use the smartest built-in tools each platform has to offer. Most importantly, we connect your data directly to your business dashboards, right from the start.

Data Lakehouse Implementation

We add warehouse-grade tables, transactions and governance on top of your lake with Databricks, Snowflake or Microsoft Fabric and open formats like Apache Iceberg and Delta Lake. Databricks usually suits heavy ML and AI work, Snowflake suits SQL-first analytics teams, and Iceberg suits teams that want to switch engines later.

Advanced Analytics and Machine Learning

We build your data lake ready to feed to your AI and ML. You will not have to waste time creating separate prep steps for every new model you want to run. We help you to position smart tools that can predict what your customers want, and forecast your future demands.

Cloud Migration to Data Lakes

We move on-prem Hadoop and Cloudera clusters, file shares and legacy warehouses to Amazon S3, Azure Data Lake Storage, Databricks or Microsoft Fabric OneLake, using open table formats like Apache Iceberg and Delta Lake. We don’t move everything at once: a small batch goes first, and the rest follows only after that batch runs correctly.

Data Lake Engineering Services

We focus on the foundations of your data to ensure that it stays fast and reliable as your business grows. We don’t believe in feeding your data into generalised templates. Every business is different and therefore, we personalise and custom-engineer your storage systems to handle the bandwidth of data your business needs.

Data Lake Development Services

At Algoscale, we build your data system from scratch. We organise data for you that helps you connect with your dashboards, smart tools and softwares you already use. We create systems that help you in the long-term.

Data Lake as a Service (DLaaS)

We handle the complete setup for you, starting from the daily development, and all the behind-the-scenes maintenance needed to keep your system running at top speed. Enterprise-level data capability without hiring and training your own internal IT team.

Data lake migrations we handle.

Moving fromMoving toWhat we convert
Hadoop / Cloudera (HDFS, Hive)Amazon S3, Azure Data Lake Storage, DatabricksHive tables, Spark and MapReduce jobs, Oozie workflows
On-prem file shares and SFTP dropsAmazon S3, Azure Data Lake StorageFolder structures, file formats, ingestion schedules
Legacy data warehouses (SQL Server, Oracle, Teradata)Databricks, Microsoft FabricTables, ETL jobs, reporting feeds
Azure Synapse / ADLS Gen1Microsoft Fabric OneLakePipelines, Spark notebooks, Power BI datasets

Swipe the table sideways to see every column.

Every migration includes

  • Code conversion: SQL, stored procedures and ETL jobs rewritten for the new platform, not just copied over.
  • Data reconciliation: row counts, financial totals and key metrics checked old vs. new before anything is switched off.
  • Report continuity: Power BI, Tableau, Looker and SSRS reports keep working on day one.
  • Cost-tuned setup: warehouse sizing and workload rules set up so your first cloud bill isn’t a surprise.
  • Parallel run and rollback plan: both systems run side by side, with a tested way back if anything fails.

Benefits of data lake consulting services.

Results from data lakes and lakehouses Algoscale has put into production.

14 weeks

From kickoff to a governed lake in production

ECM Energy Services went from kickoff to production go-live in 14 weeks, with NetSuite, Fleetio, Samsara, KPA Flex and ADP landing in one medallion data lake on Azure Data Lake Storage Gen2.

80%

Less manual reporting work

Juice Ventures replaced weekly manual report pulls with real-time dashboards on one governed Databricks platform, cutting manual effort by 80%.

40%

Lower reporting infrastructure costs

Moving reporting from Power BI to Looker and streamlining data operations cut Juice Ventures’ reporting infrastructure costs by 40%.

Hear From our Clients.

Video testimonial

I’ve been tremendously impressed by their knowledge, skills and professionalism.

Neeraj and Algoscale enabled Perceptronix and my clients have the cutting edge solutions they need to solve the very real problem that they have. We really enjoy working with their development team — our projects are always well defined and managed by project leaders.

5.0
IndustryMachine learning
LocationUnited Kingdom
Watch on YouTube
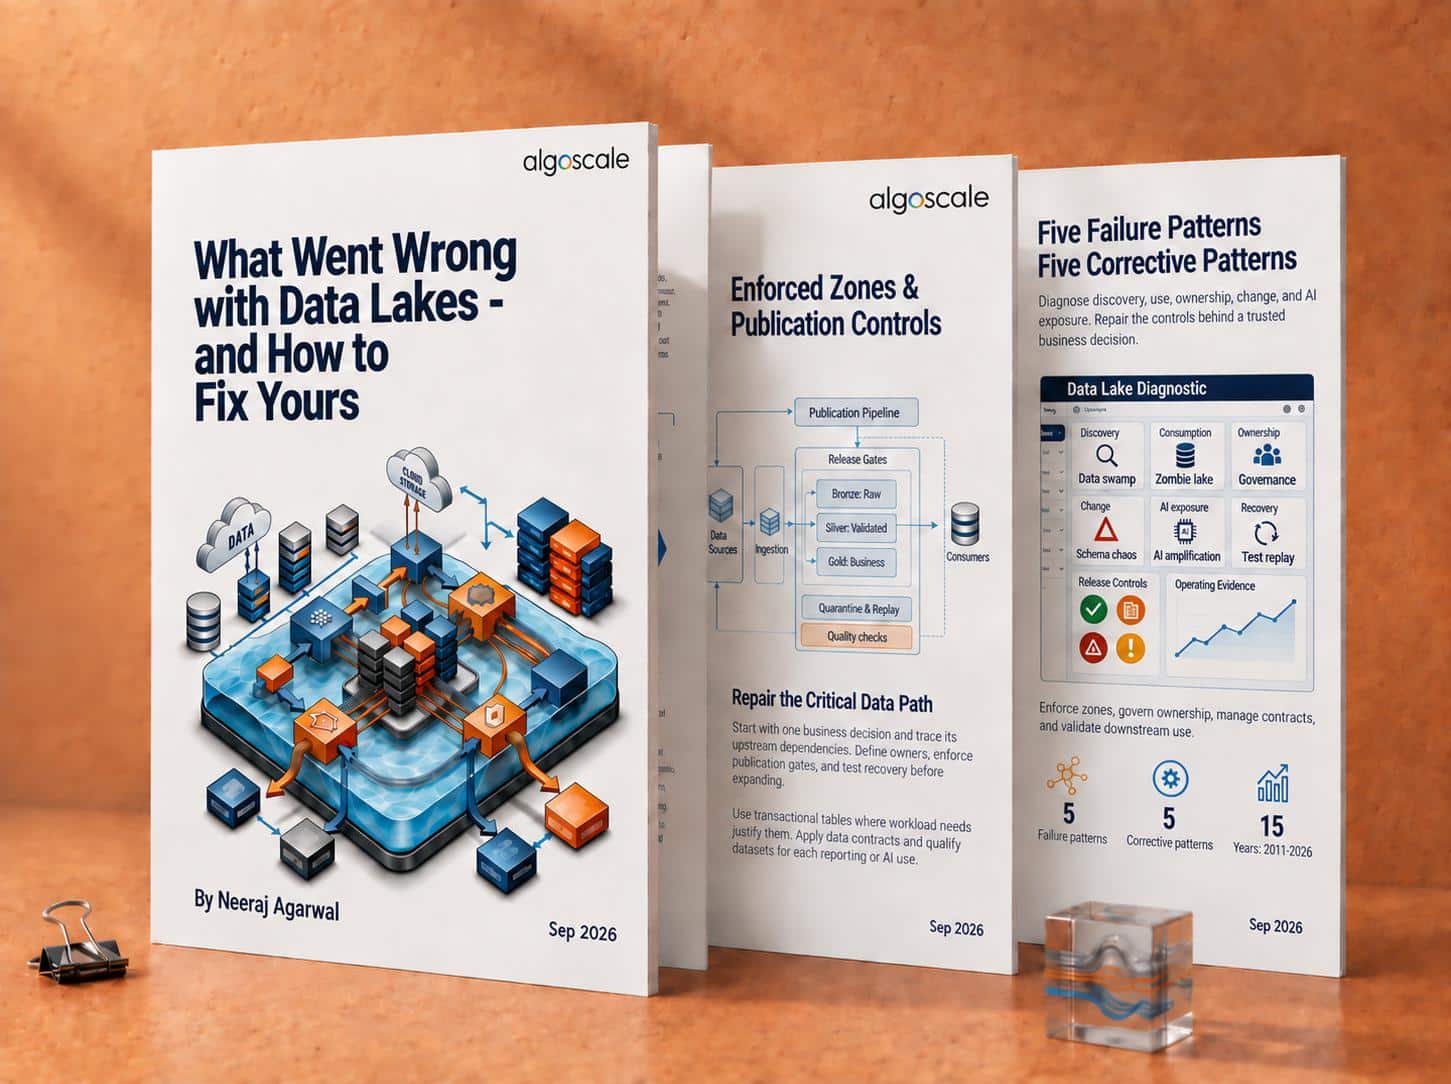
What Went Wrong with Data Lakes — and How to Fix Yours - Algoscale white paper

What Went Wrong with Data Lakes — and How to Fix Yours

Five failure patterns behind data lakes that stopped being trusted — discovery, ownership, schema drift and AI exposure — with corrective patterns for zones, governance, contracts and recovery, and a straight answer on whether to fix or rebuild.

20 pages · free PDF · no sales follow-up required

Data Warehouse vs Data Lake vs Data Lake House.

The same data can serve three different purposes, depending on what you need from it. A warehouse keeps structured data ready for fast, reliable reporting, while a lake stores raw data cheaply for analytics and AI. A lakehouse brings those approaches together, so you can work with both from the same data.

 Data WarehouseData LakeData Lakehouse
What it stores Structured, modelled data Raw, unstructured and structured data at scale Raw data with warehouse-style tables on top
Schema On write - modelled before it lands On read - structure applied when queried On read, with enforced table schemas where needed
Best for Reporting and business intelligence Big data, data science and advanced analytics BI and AI/ML on one copy of the data
Cost profile Higher per TB, compute-optimised Low-cost object storage Object storage plus a table layer
Governance Strong, built in Needs to be designed in deliberately ACID transactions, lineage and time travel
Typical tech Snowflake, Redshift, BigQuery, Synapse S3, ADLS, GCS Apache Iceberg, Delta Lake, Apache Hudi

Algoscale's data lake consulting process.

A five-stage engagement: we frame the problem against your business goals, orchestrate the architecture, run batch and real-time pipelines at scale, embed governance and audit readiness, then keep tuning performance and cost long after go-live.

01

Frame the Problem

We start by aligning on what truly matters: your business goals, data challenges, and current limitations. This includes assessing your existing systems, identifying bottlenecks, and defining clear success metrics before any architecture decisions are made.

You get: a written assessment of your sources, goals and success metrics, with a platform recommendation.

02

Orchestrate the Architecture

Next, we design a scalable, future-ready architecture tailored to your needs. Whether it’s a data lake, or lakehouse approach, we orchestrate the right combination of tools, platforms, and data flows to ensure performance, flexibility, and governance.

You get: the target architecture, a table format choice and a migration plan sequenced by source.

03

Run Data Pipelines at Scale

We build and deploy robust data pipelines that handle both batch and real-time workloads. From ingestion to transformation, everything is engineered for reliability, speed and consistency, ensuring your data is always ready when you need it.

You get: production batch and streaming pipelines with quality checks, plus reconciliation reports.

04

Govern with Confidence

We embed governance, security, and compliance into the foundation. With strong access controls, data lineage, quality checks and audit readiness, your platform stays secure, compliant, and trustworthy as it scales.

You get: an access-control matrix, lineage and audit logging, documented in your catalog.

05

Evolve & Optimize Continuously

A data platform isn’t static. We continuously monitor performance, optimize costs, and refine architecture based on real usage patterns, ensuring your system keeps improving as your data and business grow.

You get: monitoring and alerts, plus regular cost and performance reviews.

Why Choose Algoscale for Data Lake Consulting Services.

Our expertise, experience and unparalleled support makes us stand out from other data lake consultants

12+

Years of Experience

Over 12 years of experience helping businesses solve complex data, analytics, AI, and software challenges.

150+

Projects Delivered

150+ projects delivered across industries, solving diverse business challenges from data modernization to analytics and AI.

Data Privacy & Compliance

Build data lake solutions with security and governance aligned to HIPAA, PCI-DSS, SOX, GDPR, and ISO 27001 requirements.

End-to-End Data Expertise

Get end-to-end support across data strategy, governance, engineering, warehousing, lakehouses, analytics, and AI from one team.

Full Support With SLAs

Get support before and after delivery, including ongoing fixes, enhancements, monitoring, alerts, and new requirements, backed by SLAs.

Award-Winning & 5-Star Rated

Recognized by Clutch as a Champion and Global 2025 winner, with 5-star ratings and recognition among leading data analytics companies.

Tools We Work With.

The platforms we build on, migrate between, and optimise daily.

AWSStorage, catalog, query
Microsoft AzureStorage, catalog, query
Google CloudStorage, catalog, query
DatabricksProcessing & ML
SnowflakeWarehousing layer
Microsoft FabricUnified analytics
Apache SparkDistributed processing
dbtTransformation
AirflowOrchestration
Apache KafkaStreaming ingestion
Amazon RedshiftWarehousing layer
Azure SynapseServing layer

Our data experts.

Data lake engagements at Algoscale are led by Neeraj Agarwal, Architect & Practice Lead, and Tanmay Agrawal, Solutions, Data.

Neeraj Agarwal, Architect & Practice Lead at Algoscale

Neeraj Agarwal

Architect & Practice Lead

Leads data lake and lakehouse engagements across AWS, Azure, Databricks and Microsoft Fabric.

LinkedIn
Tanmay Agrawal, Solutions, Data at Algoscale

Tanmay Agrawal

Solutions, Data

Leads solution design and scoping for data lake projects.

LinkedIn

Frequently asked questions.

Get clear answers on what’s included, which platforms we work with, migration, ongoing support, and how data lakes compare with warehouses.

We look at your data, workloads, and existing systems first. A data lake gives you flexibility, a warehouse suits structured analytics, while a lakehouse brings both approaches together for broader workloads.
We usually see it when teams struggle to find or trust data. Ownership becomes unclear, quality drops, metadata is missing, and people start creating duplicate datasets to get reliable answers.
Engagements usually start around $30,000. The final cost depends on your data sources, migration needs, integrations, governance and platform. Cloud storage and compute are billed separately by your provider (AWS, Azure or Google Cloud) based on volume and usage. Most engagements begin with a 2-week audit that ends in a fixed-scope estimate. For a quick number, try our engagement estimator.
You can build one internally with the right expertise. We usually help when the architecture needs to be right from the start, costly mistakes need avoiding, or implementation needs to move faster.
We don't believe you should be locked into one platform. We work across AWS, Microsoft Azure, and Google Cloud, selecting technologies around your workloads, existing investments, and long-term requirements.
We can deliver focused implementations in a few weeks. Larger enterprise projects take several months, particularly when they involve multiple data sources, legacy migration, integrations, governance, and complex workloads.
We start by assessing your existing systems, data, and dependencies. Then we design the target architecture, establish secure connections, migrate data in stages, and validate it before moving workloads across.
We build governance into the architecture from the beginning. That covers access, security, data quality, lineage, retention, and auditing, with the same controls maintained as your data environment evolves.
We build data lakes across AWS, Microsoft Azure, and Google Cloud. Our teams also work with Databricks, Microsoft Fabric, Snowflake, Apache Iceberg, Delta Lake, and Hudi.
All three add database-style tables, updates and time travel on top of low-cost object storage. Delta Lake is the default on Databricks and Microsoft Fabric. Iceberg is the most engine-neutral choice and works well with Snowflake, AWS and multi-engine setups. Hudi fits heavy streaming and upsert workloads. We pick based on your query engines and how often your data changes.
Neither owns it. A data lake is an architecture you can build on any cloud. Databricks builds lakehouses on top of your own cloud storage (Amazon S3, Azure Data Lake Storage or Google Cloud Storage). Microsoft offers Azure Data Lake Storage Gen2 and OneLake, the data lake built into Microsoft Fabric, which runs on ADLS Gen2.
Bring us your business goals, data sources, existing systems, reporting needs, and compliance requirements. That's enough to start. We can work through the architecture, priorities, and roadmap together during discovery.
Algoscale brings 12+ years of experience and 150+ delivered projects. We’re an AWS Advanced Tier Services Partner, a Microsoft Solutions Partner for Data & AI (Azure), a Snowflake Select Partner and a Databricks Bronze Partner, with data platforms in production for clients like ECM Energy Services and Juice Ventures.
Yes. We continue supporting many environments after go-live, covering monitoring, troubleshooting, performance, cost optimization, governance, and improvements as your data platform grows and new requirements come up.
Yes. We can transfer ownership through documentation, training, and knowledge transfer. Your team can manage the platform independently, while we remain available when you need deeper technical expertise.
We use data lakes when flexibility and varied data types matter. Warehouses are better suited to structured analytics. In many projects, we use both because each serves a different workload.
Algoscale is headquartered in Newark, New Jersey, with delivery teams in Dubai and Noida, India. US clients are managed from our Newark office.
Clutch 5.0 / 5 · 12 reviews ISO 27001ISO 27001Clutch Champion 2025Clutch Champion 2025Clutch Global 2025Clutch Global 2025Best Data Analytics Companies 2025Best Data Analytics Companies 2025

Contact Us.

Tell us what you are trying to solve. A member of our team will get back to you with next steps, not a brochure.

Our customers

AccentureMintWalmartKPI PartnersGupshupImpendiCapital OneAbzoobaSupplyCopiaUST

Certified partners

Certifications

ISO 27001ISO 27001Clutch Champion 2025Clutch Champion 2025Clutch Global 2025Clutch Global 2025Best Data Analytics Companies 2025Best Data Analytics Companies 2025
Top AI Development Company BusinessFirms Certified Company WADLINE Software Badge Top Software Developers New Jersey Software Development Companies Top Custom Software Development Companies 2026 Top Software Outsourcing Companies USA BI & Big Data Development Leader 2025 Artificial Intelligence Company of the Year 2025