Every data leader eventually faces this question: Databricks or Snowflake? Both are category-defining platforms, both raised the bar for what a modern data stack should do, and both now claim to do almost everything SQL analytics, data engineering, machine learning, governance, and AI.
That overlap is exactly what makes the decision hard. A few years ago the choice was simple: pick Snowflake for warehousing, pick Databricks for data science. In 2026, that line has blurred. Snowflake has added Python UDFs, streaming ingestion, and Cortex AI. Databricks has added BI-optimized SQL warehouses, serverless compute, and even a transactional database layer with Lakebase.
At Algoscale, we help enterprises design data platforms that fit their actual workloads — not the vendor’s marketing pitch. This guide breaks down how Databricks and Snowflake really differ in 2026, where each one wins, and how to think through the decision for your own stack.
1. Two Different Starting Points
Understanding where each platform came from explains why it behaves the way it does today.
● Databricks was founded by the original creators of Apache Spark. It began as a distributed compute engine for large-scale data engineering and machine learning, and later added a warehousing layer on top — the Lakehouse architecture.
● Snowflake was built from day one as a fully managed cloud data warehouse, with a pioneering architecture that separated storage from compute. It later expanded outward into engineering, streaming, and AI.
That heritage still shows up in how each platform feels to use, who it’s built for, and where it performs best.

Architecture comparison: Databricks Lakehouse vs Snowflake Warehouse
2. Architecture at a Glance
| Dimension | Databricks (Lakehouse) | Snowflake (Cloud Warehouse) |
| Core model | Open lakehouse — one copy of data serves BI, engineering, and ML | Managed warehouse with separated storage and compute |
| Storage format | Delta Lake (open-source), Iceberg support | Proprietary micro-partitioned storage, plus native Iceberg tables |
| Compute engine | Apache Spark with Photon (vectorized engine) | Virtual Warehouses — independent, isolated SQL compute clusters |
| Best-suited data | Structured, semi-structured, and unstructured (logs, images, streams) | Structured and semi-structured (tables, JSON/VARIANT) |
| Governance layer | Unity Catalog | Horizon (governance, lineage, access control) |
| Operational model | More configurable; serverless options reduce manual tuning | Fully managed — no clusters to size or patch |
| Newest expansion | Lakebase (serverless Postgres for OLTP, via Neon acquisition) | Cortex AI, Snowpipe Streaming, native Iceberg tables |
The takeaway: Databricks gives you one flexible platform for everything from raw files to ML models. Snowflake gives you a highly polished, low-maintenance environment optimized for governed SQL analytics. Recent additions Snowflake’s Cortex AI, streaming ingestion, and native Iceberg support, alongside Databricks’ Lakebase for transactional workloads show both vendors converging toward a similar full-stack vision, even as their underlying architecture stays distinct.
3. Performance: It Depends on the Workload
Vendor benchmarks rarely agree, because the two platforms are optimized for different jobs.
● Concurrent BI and dashboarding: Snowflake’s virtual warehouse design isolates compute per workload, which avoids the queue contention that can affect shared clusters, and in several independent tests it has outperformed Databricks on core analytics queries served to many concurrent users.
● Large-scale ETL, streaming, and ML training: For big, heavy processing jobs ETL over huge datasets, model training, and streaming pipelines — Databricks has generally come in noticeably cheaper and faster than Snowflake in third-party comparisons.
In short: Snowflake tends to win when hundreds of analysts are hitting the same dashboards. Databricks tends to win when your workload is compute-heavy, custom pipelines or model training. Your own proof-of-concept, run against real workloads and real query patterns, will always be more reliable than any published benchmark.
4. Pricing Philosophy
| Factor | Databricks | Snowflake |
| Pricing unit | DBUs (Databricks Units) — bundles compute, management, and platform features | Credits, consumed per second of virtual warehouse activity |
| Cloud infra cost | Billed separately by your cloud provider (AWS/Azure/GCP), on top of DBUs | Bundled into Snowflake’s credit pricing |
| Predictability | Variable — depends heavily on cluster type and workload optimization | More predictable for steady BI and ad-hoc SQL workloads |
| Idle cost control | Serverless options cut idle-time cost, at a small per-DBU premium | Auto-suspend/auto-resume on virtual warehouses limits idle spend |
| Best economics for | Large batch ETL, ML pipelines, well-tuned clusters | Steady, predictable BI and reporting workloads |
As a rule of thumb, Databricks tends to win on price-performance for large batch ETL and ML pipelines when clusters are properly optimized, though its cloud compute costs stack on top of DBU charges. Snowflake, on the other hand, is often the more cost-predictable option for steady BI and ad-hoc SQL because of its simpler credit-based model. Neither platform is “cheaper” in absolute terms the winner depends entirely on how your workloads are shaped, and how disciplined your team is about right-sizing compute.
5. Governance, Security, and Data Sharing
Both platforms take enterprise governance seriously, but they approach it differently:
● Snowflake offers mature, governed data sharing through its Marketplace and Data Clean Rooms a strong fit if your priority is securely sharing data across business units or with external partners.
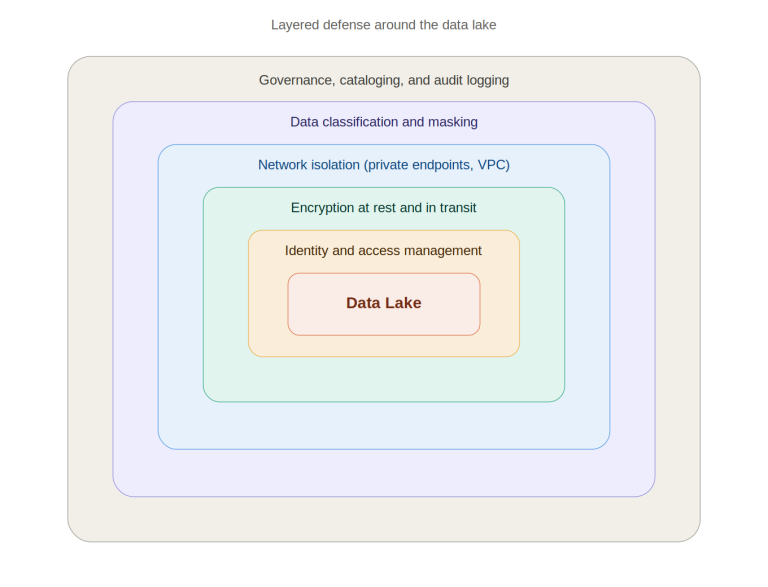
● Databricks centralizes governance for data and AI assets tables, files, models, and notebooks through Unity Catalog, which matters if you’re consolidating a data lake and a warehouse into one governed environment.
Both platforms support Apache Iceberg today, which is a meaningful shift: keeping your data in an open table format reduces vendor lock-in and makes it realistic to run a multi-engine architecture for example, Databricks for heavy transformation, Snowflake for BI without a full re-platform later.
6. Where Each Platform Naturally Fits
| Choose Databricks if you… | Choose Snowflake if you… |
| Run complex pipelines over petabyte-scale, semi-structured, or unstructured data | Need fast, governed SQL analytics for business teams |
| Need unified batch + real-time / streaming processing | Want a fully managed platform with minimal ops overhead |
| Are training or deploying ML/AI models at scale | Prioritize governed data sharing across teams or partners |
| Want to consolidate a data lake and warehouse into one architecture | Have a primarily SQL-first analyst and BI workforce |
| Are comfortable managing compute clusters for cost efficiency | Want predictable, credit-based billing for steady workloads |
Many enterprises don’t actually choose just one. A common pattern we see at Algoscale is Databricks handling ingestion, transformation, and ML, with Snowflake serving governed BI and reporting on top connected through an open table format like Iceberg or Delta.
7. A Practical Decision Framework
Before committing, walk through these questions with your team:
- What’s your dominant workload? Heavy ETL/ML → lean Databricks. Concurrent SQL/BI → lean Snowflake.
2. What data types are you working with? Mostly structured tables → Snowflake is simpler. Structured + unstructured + streaming → Databricks is more natural.
3. Who’s using the platform day-to-day? Data engineers and ML teams → Databricks. Business analysts and SQL users → Snowflake.
4. How much operational overhead can your team absorb? Snowflake’s fully managed model reduces tuning work; Databricks rewards teams that can optimize clusters.
5. What’s your governance and sharing model? Cross-org data sharing and marketplaces → Snowflake. Unified governance across data and AI assets → Databricks.
6. Are you keeping data in an open format? If yes, you preserve the option to run both platforms side by side, or switch later, without a costly re-platform.
8. The Algoscale Perspective
There’s no universal winner between Databricks and Snowflake, only the right fit for your workloads, team skills, and roadmap. What matters most is running a proof-of-concept against your actual data and queries, not a generic benchmark, before making a platform bet that will shape your data architecture for years.
At Algoscale, we help organizations evaluate, implement, and optimize both platforms from architecture design and migration to cost governance and AI enablement. If you’re weighing Databricks against Snowflake for your next data platform decision, our data engineering team can help you run a structured evaluation and land on the option that actually fits your stack.
Ready to build a data platform that scales with your business? Talk to Algoscale’s data engineering experts to get started.